Running local Large Language Models (LLMs) via Ollama offers unprecedented privacy and control for tech enthusiasts and enterprise developers alike. However, as you engage in extended multi-turn AI conversations, you might notice your system hardware struggling under sudden, severe memory pressure. This bottleneck rarely stems from the base model weights; instead, the primary culprit is often unconstrained Key-Value (KV) cache memory consumption. When you limit local KV cache RAM usage, you protect your system from brutal Out-of-Memory (OOM) crashes and preserve critical system resources. In this comprehensive guide, we will break down the exact mechanisms behind KV caching, explore why multi-turn chat sessions consume so much memory, and walk step-by-step through configuring your Ollama instance for maximum stability and performance.
Understanding the KV Cache in Local LLMs
To understand why your GPU VRAM or system RAM fills up so quickly, you must first understand how transformers handle token context. During AI inference, the model reads the entire prompt to predict the next token. If the model had to re-process every preceding token in a long chat history for every new word generated, generation speed would crawl to a complete standstill.
To solve this computational bottleneck, modern inference engines store intermediate mathematical states—specifically the Key and Value matrices—in memory. This temporary memory store is known as the KV Cache. By saving these calculations, the model simply looks up past context instantly, maintaining impressive tokens-per-second generation speeds even during complex interactions.
However, this speed boost comes at a steep physical memory cost. Unlike the model’s static weights, which consume a fixed amount of RAM upon boot, the KV cache grows dynamically with every single message exchanged in a session.
- Static Model Weights: The baseline VRAM/RAM required just to load the quantized model files into memory.
- Dynamic KV Cache: Memory allocated continuously to retain prompt context, chat history, and tokens generated throughout your active session.
Because context windows on modern architectures like Llama 3 or Qwen 2.5 expand up to 32k, 64k, or even 128k tokens, an unconfigured KV cache can easily exceed the size of the base model itself. Consequently, your GPU offloading spills over into host system memory or triggers driver crashes.
Why Multi-Turn Conversations Explode Memory
In a single-turn prompt—such as asking the AI to reformat a short code block—the context window closes immediately after generation finishes. Memory allocations remain relatively small and predictable. In sharp contrast, multi-turn AI conversations demand continuous context preservation across back-and-forth prompt iterations.
As your conversation deepens, your client interface passes the entire prior conversation history back to the Ollama server alongside your newest prompt. The server must extend the KV cache to accommodate the expanded token sequence. This linear growth rapidly degrades available VRAM on consumer GPUs like NVIDIA RTX cards or Apple Silicon unified memory systems.
Furthermore, concurrent operations amplify this memory requirement exponentially. If you use your local server as a backend for automated scripting tools, browser extensions, or multi-user web interfaces (such as Open WebUI), Ollama defaults to allocating separate context allocations for parallel requests.
⚠️ Warning: Running concurrent streams without explicitly capping memory parameters can instantly trigger system swapping, slowing generation from dozens of tokens per second down to single digits.
Method 1: Tuning the Context Window with num_ctx
The most direct way to control KV cache size in Ollama is by setting the context window limit. By default, Ollama assigns a standard 4096-token context window (num_ctx) to most models. However, third-party web clients often request massive 32k or 64k contexts automatically, forcing Ollama to pre-allocate massive KV buffers. Capping your num_ctx is essential for tight Ollama memory management guide workflows.
1. Adjusting Modelfile Parameters
You can permanently restrict a model’s maximum context by creating a custom Modelfile.
Create a plain text file named Modelfile with the following contents:
Dockerfile
FROM llama3.2
PARAMETER num_ctx 4096
Next, open your terminal and build the new model variant:
Bash
ollama create llama3-custom -f ./Modelfile2. Passing Parameters via CLI or API
If you prefer running models ad-hoc through the terminal, you can set the parameter interactively:
Bash
/set parameter num_ctx 4096When integrating Ollama into custom scripts via its REST API, pass the num_ctx explicitly inside your payload options:
JSON
{
  "model": "llama3.2",
  "prompt": "Summarize the log output above.",
  "options": {
    "num_ctx": 4096
  }
}
💡 Pro-Tip: Dropping your context length from 32,768 tokens down to 8,192 tokens can free up anywhere from 4 GB to 12 GB of VRAM during extended chat sessions!
Method 2: Optimizing Server-Level Environment Variables
While model parameters control individual chat instances, global environment variables let you enforce platform-wide limits across the entire Ollama service. These global variables ensure that no background application forces your server into hardware-exhausting memory consumption.
Global Context Overrides
You can force Ollama to respect a default context window across all incoming client connections by configuring OLLAMA_CONTEXT_LENGTH.
- Linux (Systemd): Run
sudo systemctl edit ollama.serviceand append:Ini, TOML[Service] Environment="OLLAMA_CONTEXT_LENGTH=4096" - macOS (Terminal):Bash
launchctl setenv OLLAMA_CONTEXT_LENGTH 4096 - Windows (PowerShell):PowerShell
[System.Environment]::SetEnvironmentVariable('OLLAMA_CONTEXT_LENGTH', '4096', 'User')
Restricting Parallel Request Allocation
By default, Ollama attempts to handle multiple incoming prompts concurrently. The environment setting OLLAMA_NUM_PARALLEL dictates how many parallel requests each model can process at once. Crucially, memory consumption scales linearly with OLLAMA_NUM_PARALLEL * OLLAMA_CONTEXT_LENGTH.
If your home setup only serves your personal work, set this variable strictly to 1:
Bash
OLLAMA_NUM_PARALLEL=1By constraining parallel processing, you prevent your KV cache allocations from duplicating and stealing precious VRAM away from your core model layers.
Method 3: Enabling KV Cache Quantization
If you must run expansive context windows without sacrificing VRAM, modern inference backends like llama.cpp (which powers Ollama natively) support Ollama KV cache RAM optimization through KV cache quantization.
By default, the KV cache stores context numbers at 16-bit floating-point precision (f16). However, you can compress these stored states into 8-bit (q8_0) or 4-bit (q4_0) precision with virtually imperceptible loss in output quality.
To enable KV cache quantization in Ollama, set the following environment variable on your system:
Bash
OLLAMA_KV_CACHE_TYPE=q8_0Memory Savings Breakdown
| Cache Precision Type | VRAM Usage per 10k Context | Perceived Output Quality | Recommended Hardware Target |
| f16 (Default) | ~2.0 GB – 3.0 GB | 100% (Baseline) | High-end GPUs (24GB+ VRAM) |
| q8_0 (Quantized) | ~1.0 GB – 1.5 GB | ~99.5% (Indistinguishable) | Mid-range GPUs (8GB – 16GB) |
| q4_0 (Quantized) | ~0.5 GB – 0.8 GB | ~97.0% (Minor degradation) | Low VRAM / Embedded systems |
Setting OLLAMA_KV_CACHE_TYPE=q8_0 instantly cuts your KV cache RAM footprint roughly in half, enabling vastly extended conversation histories without needing expensive hardware upgrades. You can learn more about inference optimizations on the Official PyTorch Blog.
Monitoring Real-Time VRAM & System Usage
Once you apply these configurations, you need to verify that your memory optimizations are taking effect in active workloads.
Run the Ollama process monitor in your command prompt while initiating a long multi-turn chat session:
Bash
ollama psThe terminal output will display your active model, its current allocated processor split (GPU vs. CPU), and its active session context length:
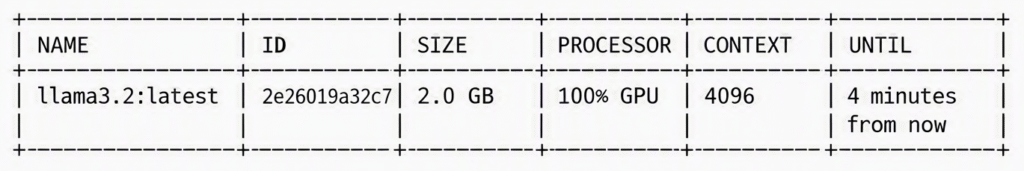
If the PROCESSOR column displays 100% GPU, your model and its entire KV cache fit securely inside your dedicated graphics card memory. However, if you see partial split offloading—such as 70%/30% CPU/GPU—it means your combined model weights and KV cache exceeded VRAM capacity, pushing heavy computations onto your system’s slower CPU RAM.
In that scenario, lower your num_ctx or switch to q8_0 KV quantization to force the processing pipeline back into GPU memory completely.
Final Thoughts & Recommended Configuration
Managing memory parameters when running local LLMs is a delicate balancing act. While huge context windows offer impressive capabilities, runaway RAM usage quickly destroys your system’s output speed. By taking control of parameters like num_ctx, setting OLLAMA_NUM_PARALLEL=1, and utilizing quantized cache options like q8_0, you maintain lightning-fast response times even during deep, multi-turn AI conversations.
Experimentation is key to discovering the ideal balance for your hardware layout. Standardizing your setup around 4,096 to 8,192 context tokens generally yields the best sweet spot between memory consumption and contextual recall.
How do you manage memory allocations on your local AI server? Drop your thoughts, questions, or benchmark results in the comments below! If you found this guide helpful, don’t forget to share it with fellow developers and local LLM enthusiasts.